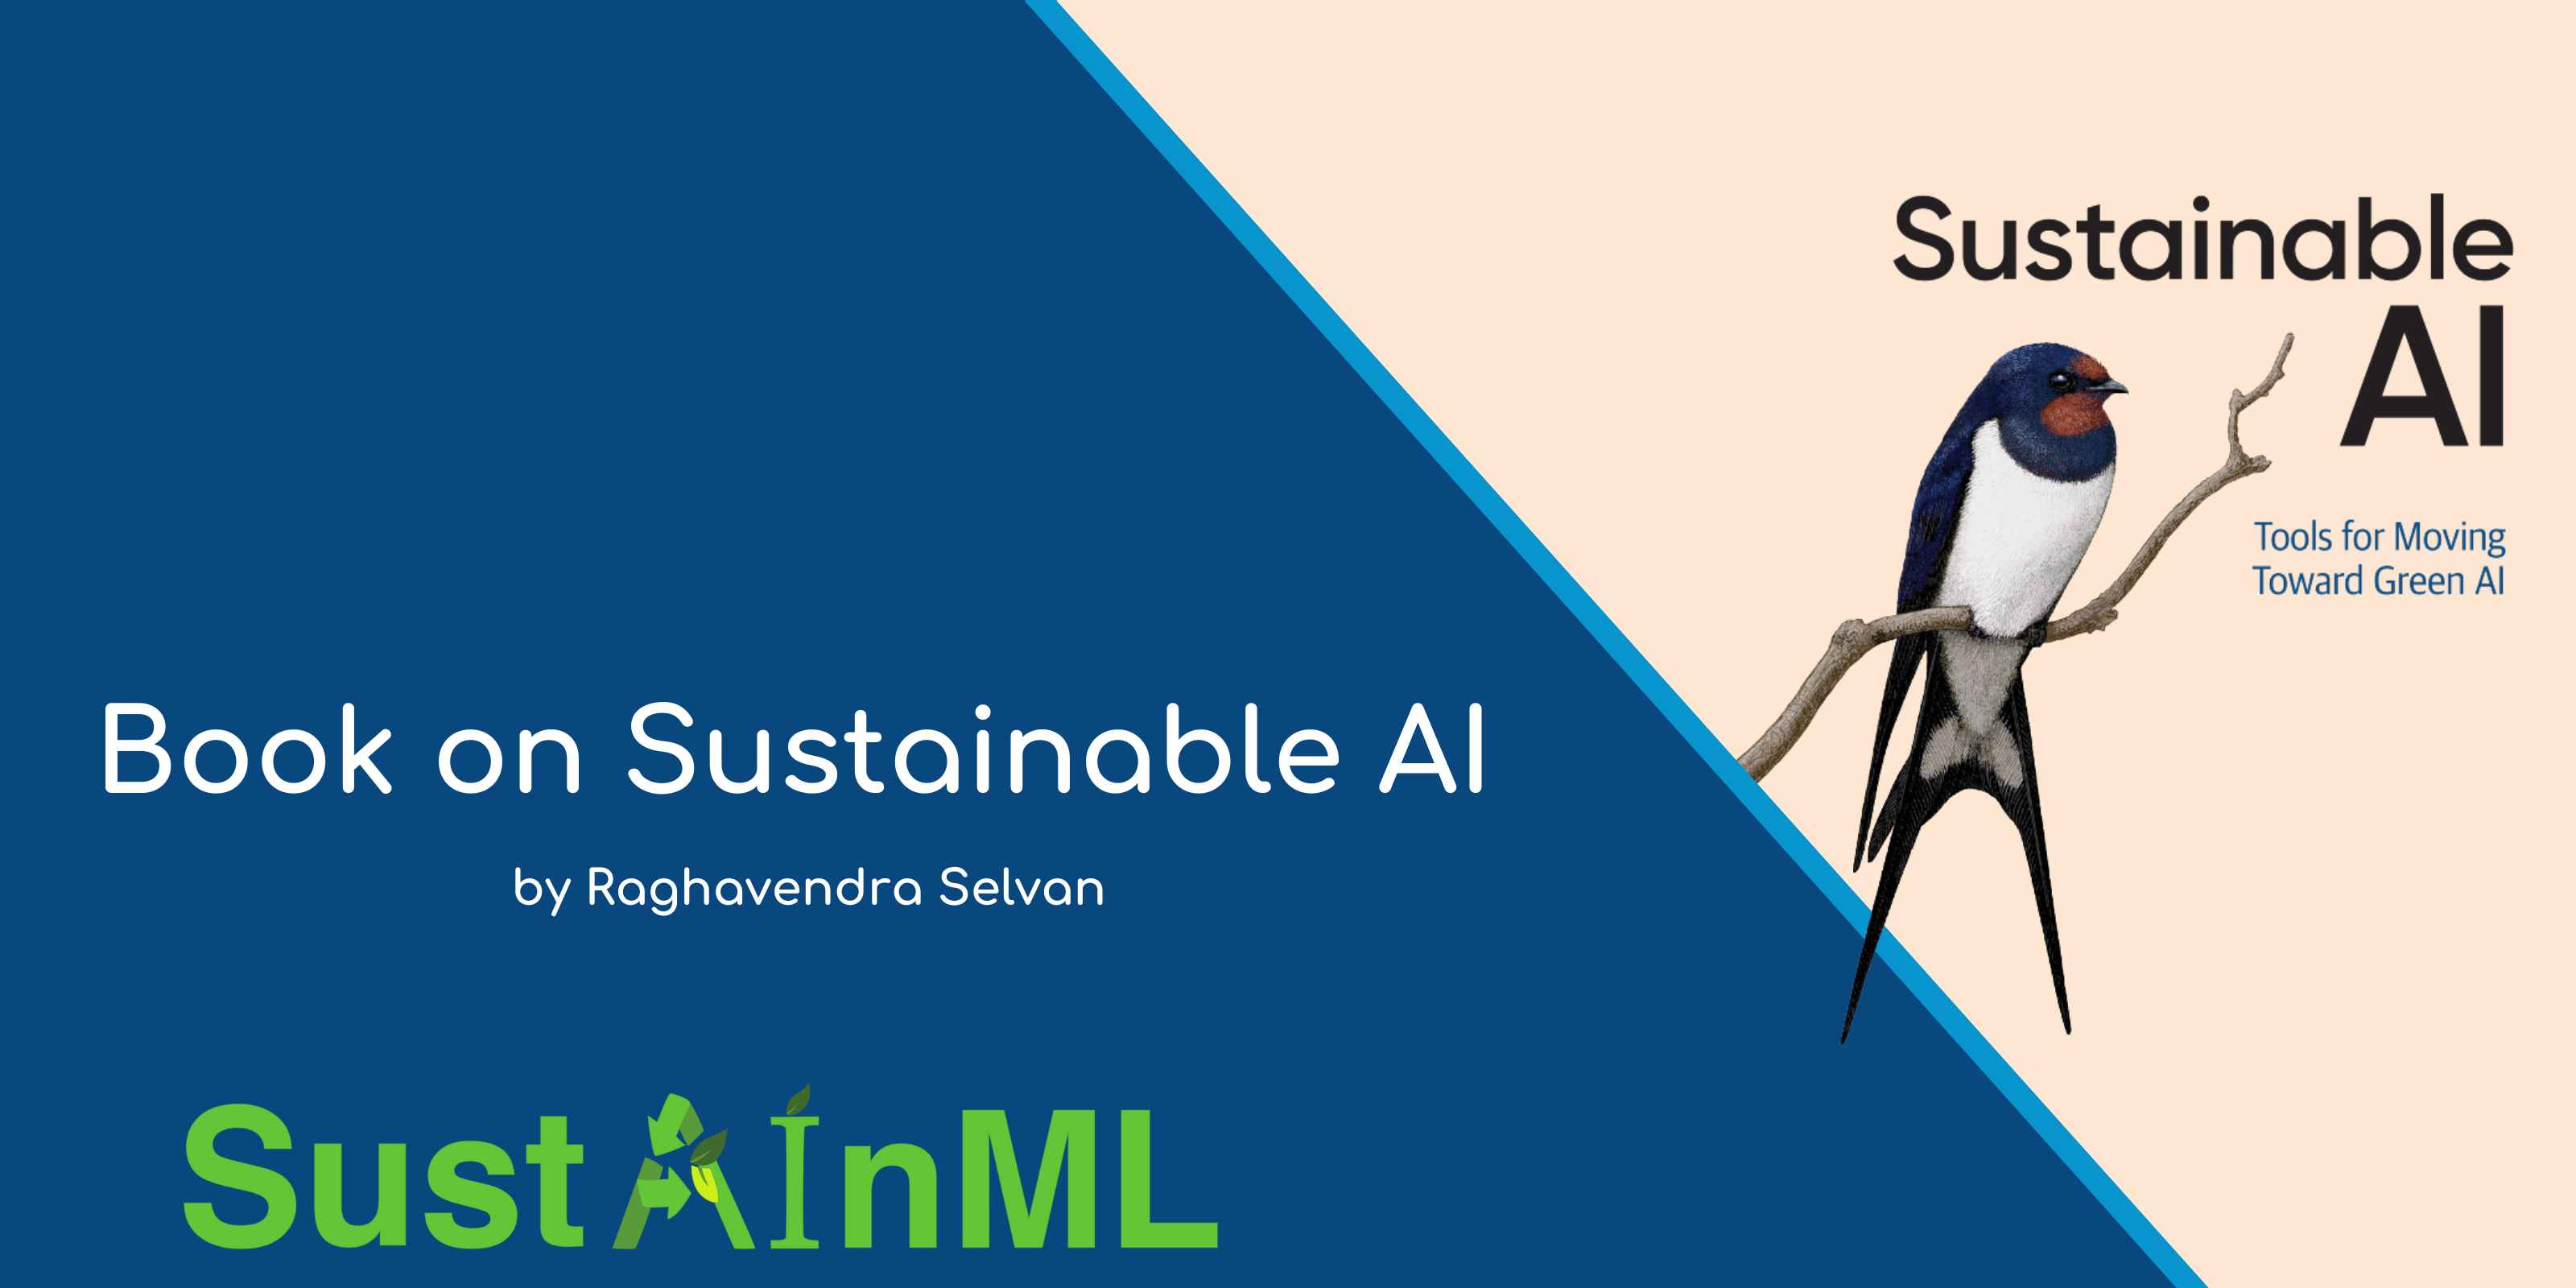
The SustainML project is pleased to spotlight the publication of Sustainable AI: Tools for Moving Toward Green AI, a new book by Raghavendra Selvan that directly addresses one of SustainML’s core concerns: how to harness the power of modern AI while dramatically reducing its environmental and social footprint.
In a world already locked into dangerous levels of planetary warming, artificial intelligence has become both a promising ally and a new source of environmental pressure. Sustainable AI: Tools for Moving Toward Green AI by Raghavendra Selvan takes this tension seriously. It argues that we cannot talk about “AI for good” without also accounting for the material footprint of the AI itself – the energy, hardware, water, and labour that sit behind every model we train and deploy.
The book starts from the simple but uncomfortable observation that the current wave of data-hungry, compute-intensive deep learning is on a collision course with climate targets. Large models demand hyperscale datacentres, which in turn require massive electricity, cooling water, and specialised hardware manufactured through resource-intensive global supply chains. At the same time, AI is increasingly proposed as a key tool for climate mitigation and adaptation. Selvan’s central question is therefore not “Can AI help with sustainability?” but “Under what conditions does AI itself become sustainable enough to justify its use?”.
From the climate crisis to AI practitioners’ responsibilities
The early chapters set the stage by outlining where we are in the climate crisis and why a narrow focus on efficiency or “green growth” is no longer sufficient. The book adopts the UN definition of sustainability, meeting present needs without compromising future ones, and insists this must be applied to AI as rigorously as to energy, transport or agriculture.
Selvan also clarifies terminology: AI as the broad sociotechnical project; machine learning as the data-driven methods inside it; and deep learning as the neural-network subset that powers today’s generative models. This framing matters because the environmental discussion is really about a specific style of AI, large-scale deep learning, rather than “intelligence” in the abstract.
Crucially, the book is written for practitioners: engineers training models, teams deploying systems, managers commissioning AI projects, and policymakers trying to understand the trade-offs. It is neither a popular-science overview nor a formal textbook; instead, it combines conceptual frameworks with practical tools that can be dropped into existing ML workflows.
Making the footprint of AI visible
A recurring theme is that sustainability must be measured before it can be meaningfully improved. The book, therefore, introduces concrete ways to quantify the resource consumption of AI:
- Model complexity: parameters, FLOPs and algorithmic choices that determine the raw amount of computation required.
- Runtime and energy: the bridge from abstract complexity to real-world electricity use, hardware utilisation and latency.
- Carbon footprint: translating energy into greenhouse gas emissions using grid carbon intensity, and distinguishing between operational emissions and embodied emissions from hardware manufacturing and infrastructure.
Selvan introduces the ideas of AI waste, unnecessary or avoidable resource use, and resource pyramids, which help practitioners see how small design choices at the model level propagate into energy and emissions at the data centre scale. These concepts are used throughout the book to question “business as usual” practices, such as training huge models from scratch when smaller, pretrained or distilled models would suffice.
Practical interventions across the ML lifecycle
The core of Sustainable AI walks step by step through the modern AI lifecycle, always asking: Where are the biggest resource bottlenecks, and what can we do about them?
- Data parsimony (Chapter 4)
The book challenges the “more data is always better” mindset. It shows how careful dataset curation, active learning, instance selection, tokenisation strategies, and dataset condensation can reduce storage, labelling and training costs, without sacrificing performance. The message is not to starve models of data, but to treat data as a costly resource rather than an infinite free good. - Automated model selection (Chapter 5)
Hyperparameter optimisation and neural architecture search are reframed through a sustainability lens. Instead of chasing marginal accuracy gains at any cost, Selvan advocates multi-objective optimisation: finding configurations on the Pareto frontier that balance performance with compute, memory, latency and energy. The proposed “MC³-space” (model class, configuration, and compute) helps practitioners reason about where in the search space they are spending their resources. - Training efficiency (Chapter 6)
Training is often the most visible cost. Here, the book surveys transfer learning, fine-tuning, in-context learning, network pruning, low-rank adaptation (LoRA) and quantisation-aware training. The emphasis is on techniques that reuse existing computation or reduce precision safely, so that most projects never need to run months-long, frontier-scale training runs. - Lean inference (Chapter 7)
Even modest models, when deployed at scale, can consume more energy in inference than in training. Selvan introduces the idea of the lifetime cost of a model and shows how knowledge distillation, post-training quantisation, architecture choices and deployment in low-level languages can dramatically reduce per-query costs. The chapter is particularly relevant for organisations running edge deployments or real-time services. - Hardware and infrastructure (Chapter 8)
Moving beyond algorithms, the book addresses cluster-level scheduling, accelerator-level optimisation, and the environmental cost of hardware cycles and e-waste. It highlights under-utilisation as a major source of AI waste and describes practical strategies, such as better workload colocation and model-/data-parallel schemes, to get more useful work out of existing machines.
Throughout these chapters, real-world use cases, ranging from climate-related applications to medical imaging, illustrate how the techniques can be applied in practice rather than staying at the level of abstract principles.
Operationalising Sustainable AI in organisations
Recognising that most AI systems are built by teams rather than individuals, Sustainable AI devotes a full chapter to operationalisation. It links the emerging practice of MLOps with “Green MLOps”, arguing that sustainability metrics should sit alongside accuracy, latency and reliability in our pipelines.
Concrete suggestions include:
- Model cards that document not just performance and data, but also resource usage and known environmental trade-offs.
- Energy ratings and standardised reporting of compute, energy and emissions for major training runs.
- Orchestration frameworks that integrate carbon-aware scheduling, monitoring and decommissioning into routine workflows.
For a project like SustainML, these ideas speak directly to how we design our platforms, benchmarks and best practices: not only what models do, but how they are produced and maintained.
Beyond efficiency: toward environmental, economic and social sustainability
The final chapter is deliberately cautionary. Using the example of synthetic fertilisers in the Green Revolution, Selvan introduces rebound effects: when efficiency gains make a technology cheaper or easier to use, total usage can grow so much that environmental impact increases rather than decreases. The same risk exists for AI: making models cheaper and faster can accelerate deployment in ways that overwhelm the savings.
The book, therefore, argues that efficiency is necessary but not sufficient. To talk about truly sustainable AI, we must also consider:
- Broader environmental effects that go beyond operational carbon: water use for cooling, land and materials for datacentres, and toxic by-products in supply chains.
- Economic sustainability, including the concentration of computing in a few regions and organisations, and the resulting digital divide.
- Social sustainability, from labour conditions in data labelling and hardware manufacturing to the distribution of benefits and harms across the globe.
Selvan introduces concepts such as environmental debt (the cumulative burden we build into AI systems) and advocates systems thinking, frameworks like SASA and CARAML that connect technical choices to policy, governance and justice-oriented perspectives.
Open resources and climate justice impact
Importantly for practitioners, the book is accompanied by an open GitHub repository with code examples and small utilities that make it easier to measure and reduce the footprint of real projects: logging energy use, experimenting with pruning and quantisation, and integrating sustainability metrics into existing ML pipelines.
Equally important is where the author directs the proceeds: all royalties from the book are donated to grassroots climate justice movements in the majority world. Beneficiaries include organisations such as the People’s Archive of Rural India (PARI), which documents the lives and struggles of rural communities on the frontlines of climate change. In other words, the book not only argues for more just uses of AI, but it helps resource them.
Why this matters for SustainML
For the SustainML project, Sustainable AI offers both a conceptual foundation and a toolbox. It provides language, AI waste, environmental debt, data parsimony, and green MLOps to discuss sustainability with partners and policymakers. It also provides concrete practices we can embed into our own work: from dataset curation strategies and efficient training recipes to carbon-aware deployment and reporting.
Most importantly, the book reminds us that the goal is not just “faster, cheaper, greener models”, but AI that fits within planetary boundaries while supporting more equitable futures. That is precisely the conversation SustainML aims to advance, and Sustainable AI is an excellent guide for anyone who wants to take that journey seriously.
 This project has received funding from the European Union’s Horizon Europe research and innovation programme under grant agreement No 101070408.